For quite a while now, I've been looking for a good way to run PostgreSQL in the cloud.
PostgreSQL is pretty much my workhorse. I use it in a lot of projects, I know it well, and frankly I have no desire to replace it.
I've always liked the convenience of managed services, too. Create a database, connect the application, go back to writing code. No need to spend my time worrying about backups, server updates, configurations, and everything else that comes with running PostgreSQL in production.
And I already have plenty of projects. Some are small, some are growing, and others are still experiments. When I start working on a new idea, I'd rather launch it than spend three days preparing infrastructure.
The trouble is, as the number of projects grows, so does the bill.
Especially the database bill.
I've tried different providers, including Fly.io, and looked at plenty of alternatives. It always seems to be the same story: you start with a plan that looks reasonable, increase the resources a little, add another project, perhaps need a separate database...
And there's another subscription.
At some point I started wondering if all the PostgreSQL providers had got together and agreed to raise their prices.
I'm joking, of course. But looking at some of those price lists, you do start to wonder.
How much does PostgreSQL actually cost now?
I put together a few entry-level prices from familiar services, as listed in October 2026.
| Provider | Indicative price |
|---|---|
| Fly.io Managed Postgres | From $38/month, storage excluded |
| Supabase Pro | From $25/month, first project included |
| DigitalOcean Managed PostgreSQL | From $15/month for a basic node |
| Render PostgreSQL | From $6/month for 256 MB; $19 for 1 GB RAM |
| Hetzner Cloud CAX21 | €10.49/month for an ARM64 VPS, excluding VAT and extras |
That last row isn't a managed database. Hetzner gives you a server on which to install PostgreSQL yourself. I included it deliberately, because this comparison is exactly what led me to make a change.
But seriously, look at those prices.
How can storing a couple of rows in PostgreSQL end up costing this much?
I'm not asking for a GPU to train an AI model. I want to store users, some settings, messages, documents, and a bit of application data.
Quite often, a project is still in development and doesn't even have real users. But the database is already costing money.
I understand that managed services come with automatic backups, updates, high availability, and plenty of other conveniences. I'm not saying those things are worthless.
Still, when I compare them with other cloud services, including different AWS options, I sometimes see enormous price differences. Of course you need to compare equivalent resources, reliability, and features, or the numbers don't mean very much.
But my problem remains the same: why do I have to take on another substantial fixed monthly cost every time I want to try a new application?
If a product starts making money, paying extra for managed infrastructure can make perfect sense.
When you're still figuring out whether anyone will use it, though, those costs start to sting.
And I already have more than enough ideas to test.
I finally decided to run my own server
After years of using and trying managed databases, I decided to change course.
I rented a Hetzner server and started organizing PostgreSQL and my applications' databases there.
And so far, I haven't regretted it.
In my case, I'm paying roughly $20 a month for my current setup, with resources that are more than enough for me: approximately eight cores, 24 GB of RAM, and disk space for my projects.
That's my own configuration and what I pay, not a standard advertised plan for everyone. Plans and prices change.
What matters to me is that I can now decide how to share those resources.
I can create multiple PostgreSQL databases on the same instance, give each application its own user and permissions, and scale up the machine when there's a real reason to do so.
Without automatically paying for another managed database every time I have a new idea.
There was still one thing I wasn't happy about, though.
The terminal.
Don't get me wrong: I work in it every day. But when I need to add a database, create a role, inspect connections, or check backups, I don't want to SSH into a machine and remember every command, every single time.
I want to open a page, see my databases, and do what I need to do.
That doesn't seem like an unreasonable request.
So I started looking for something that would let me run PostgreSQL on my own server without losing all the convenience of a managed platform.
That's how I found Supavisor.
And the funny part? It's written in Elixir.
Finally, something I could open, understand, and modify in my favorite language.
What is Supavisor?
Supavisor is an open-source connection pooler built by Supabase.
It's not a database. PostgreSQL still stores the data and executes the queries.
Supavisor manages the connections between applications and PostgreSQL.
For example:
Elixir application ──┐
                      │
Node.js application ─┼── Supavisor ── PostgreSQL
                      │                    │
Python application ──┘              ┌─────┼─────┐
                                    DB A  DB B  DB C
The nice thing is that Supavisor speaks the normal PostgreSQL wire protocol.
That means I can use Ecto, Postgrex, psql, psycopg, Node.js's PostgreSQL driver, or virtually any other compatible client.
I don't need to invent an HTTP API just to run a SELECT.
Supavisor mainly offers two pooling modes.
Session pooling: a PostgreSQL connection remains assigned to a client for the entire session.
Transaction pooling: a PostgreSQL connection is assigned while a transaction runs and can then be reused by another client.
The second option is particularly useful when I have lots of applications or instances that keep connections open but only use the database briefly at a time.
For example, five Phoenix instances with pool_size: 10 can open up to 50 connections. With Supavisor I can independently control how many backend connections are maintained to PostgreSQL.
Of course, that doesn't mean 50 queries can all run simultaneously through five backend connections without waiting. When the pool is busy, clients wait.
The benefit is that PostgreSQL doesn't have to keep so many unused backend connections open.
Connecting a database to Supavisor
My fork uses these ports:
5432  Direct PostgreSQL
6543  Transaction pooling
5452  Session pooling
4000  Dashboard Phoenix
Let's say we have a database called demo_db and a PostgreSQL role called demo_app.
If the database doesn't exist yet, we can create it manually:
sudo -u postgres createuser \
  --login \
  --pwprompt \
  demo_app

sudo -u postgres createdb \
  --owner=demo_app \
  demo_db
In Supavisor, we create a tenant: a connection profile identifying the database, credentials, and pool configuration.
For this example:
Tenant:       demo
Database:     demo_db
Host:         127.0.0.1
Port:         5432
Database user: demo_app
Pool size:    5
Max clients:  50
To connect through Supavisor, the username combines the PostgreSQL role and the tenant:
demo_app.demo
We can try it with psql:
psql \
  -h 127.0.0.1 \
  -p 6543 \
  -U demo_app.demo \
  -d demo_db \
  -W
Enter the password configured for the role.
If everything is set up correctly:
SELECT current_database(), current_user;
And we're talking to PostgreSQL through the pooler.
So far, nothing about how we use PostgreSQL has changed.
What about Elixir? Just configure Ecto
Once Supavisor is configured on the server, the application connects directly to the pooler's hostname. It's the same pattern I use in my own applications: the host, port, and trusted TLS certificate are provided through environment variables. No SSH tunnel is required, and my Ecto queries don't change.
Let's say I've created tenant demo for database demo_db with PostgreSQL role demo_app. The pooler username is demo_app.demo. I can configure config/runtime.exs like this:
# config/runtime.exs
import Config

if config_env() == :prod do
  hostname = System.fetch_env!("DATABASE_HOSTNAME")
  pool_mode = System.get_env("DATABASE_POOL_MODE", "transaction")

  {port, prepare} =
    case pool_mode do
      "transaction" -> {6543, :unnamed}
      "session" -> {5452, :named}
      other -> raise "Unsupported pool mode: #{other}"
    end

  config :demo, Demo.Repo,
    hostname: hostname,
    port: port,
    database: System.fetch_env!("DATABASE_NAME"),
    username: System.fetch_env!("DATABASE_USERNAME"),
    password: System.fetch_env!("DATABASE_PASSWORD"),
    pool_size: String.to_integer(System.get_env("POOL_SIZE", "5")),
    prepare: prepare,
    connect_timeout: 30_000,
    show_sensitive_data_on_connection_error: false,
    ssl: [
      verify: :verify_peer,
      cacertfile: System.fetch_env!("DATABASE_CA_CERT_FILE"),
      server_name_indication: String.to_charlist(hostname)
    ]
end
For example, on the Phoenix application server I set DATABASE_HOSTNAME=db.example.com, DATABASE_NAME=demo_db, DATABASE_USERNAME=demo_app.demo, and DATABASE_POOL_MODE=transaction. The password stays in a secret. DATABASE_CA_CERT_FILE points to a PEM file containing the trusted CA certificates used to validate the pooler's TLS certificate. For a private CA, distribute that CA to the clients; for a public certificate, use an appropriate trusted CA bundle.
The hostname must match the server certificate. With verify: :verify_peer, I don't just want an encrypted connection: I also want to verify which server I'm connecting to.
After the application starts, I can check the connection from IEx:
Ecto.Adapters.SQL.query!(
  Demo.Repo,
  "SELECT current_database(), current_user",
  []
)
This configuration connects straight to Supavisor on remote port 6543. For migrations I select DATABASE_POOL_MODE=session and use port 5452. No extra local ports are involved.
Why prepare: :unnamed?
This detail matters.
With transaction pooling, two consecutive transactions may run over two different PostgreSQL backend connections.
If a client prepares a statement with a name on one session, it cannot automatically assume that statement exists on the next session.
Configuring Postgrex with:
prepare: :unnamed
means we don't depend on named prepared statements persisting in one particular session.
Supavisor can also support named prepared statements in transaction mode, but that feature needs to be enabled and configured explicitly. I prefer starting with the simpler, more compatible behavior until I actually need something else.
It's not just for Elixir
Supavisor uses the standard PostgreSQL protocol, so other languages can connect to it directly as well. They need the same hostname, the pooler port, the role.tenant username, and a TLS connection that validates the server certificate.
For example, with Node.js I install pg:
npm install pg
const fs = require("node:fs");
const { Client } = require("pg");

async function main() {
  const db = new Client({
    host: process.env.DATABASE_HOSTNAME,
    port: 6543,
    user: "demo_app.demo",
    password: process.env.DATABASE_PASSWORD,
    database: "demo_db",
    ssl: {
      ca: fs.readFileSync(
        process.env.DATABASE_CA_CERT_FILE,
        "utf8"
      ),
      rejectUnauthorized: true
    }
  });

  await db.connect();
  const result = await db.query("SELECT 1 AS ok");
  console.log(result.rows);
  await db.end();
}

main().catch(console.error);
With Python and psycopg:
pip install "psycopg[binary]"
import os
import psycopg

with psycopg.connect(
    host=os.environ["DATABASE_HOSTNAME"],
    port=6543,
    dbname="demo_db",
    user="demo_app.demo",
    password=os.environ["DATABASE_PASSWORD"],
    sslmode="verify-full",
    sslrootcert=os.environ["DATABASE_CA_CERT_FILE"]
) as connection:
    with connection.cursor() as cursor:
        cursor.execute("SELECT current_database()")
        print(cursor.fetchone())
All three examples, Elixir, Node.js, and Python, connect straight to the same Supavisor endpoint. No intermediary HTTP service and no SSH tunnel.
But what I really wanted was a dashboard
And this is where we get to the reason I modified the project.
Supavisor was built as a connection pooler. I also wanted a simple way to administer databases from a browser.
So I forked it and added a console with Phoenix LiveView.
The code is public:
Supavisor dashboard (elchemista/supavisor)
The dashboard lets me inspect tenants, add and edit connection profiles, browse PostgreSQL databases, manage access, and watch the metrics.
I also added backup and restore operations.
One feature I find especially useful is provisioning: I can create a database, its PostgreSQL role, and its Supavisor tenant straight from the console.
Provisioning is disabled by default because it requires administrative PostgreSQL credentials. It must be explicitly enabled and restricted to approved database servers.
Otherwise, I can simply connect existing databases and roles.
For me, that's a huge difference. Instead of remembering a pile of SQL commands and parameters, I open the browser and take care of the common tasks.
Then, naturally, I started adding other things.
REST and WebSocket APIs, local embeddings through ExFastembed, mail services, and some AI features.
I know. I was only supposed to add a PostgreSQL dashboard.
Apparently I'm not very good at stopping.
But that's one of the things I like about open source: if a tool already does almost everything I need, I can change it and make it fit.
Trying it locally
To try my fork, you'll need a working PostgreSQL installation, Elixir 1.19 or later, Erlang/OTP 27 or later, and the native build dependencies.
Clone the dashboard branch:
git clone --branch ui/admin \
  https://github.com/elchemista/supavisor.git

cd supavisor
Then run:
mix setup
mix phx.server
Open:
http://localhost:4000/admin
In development, the console offers local sign-in as admin@localhost using the Sign in locally button.
The mix setup command prepares dependencies, creates the necessary Supavisor metadata database, and runs the project's migrations. It isn't the same thing as resetting the databases belonging to your applications.
From there we can explore the console and add the tenants we need.
Installing it on a Hetzner server
For deployment I decided to use an ordinary Elixir release managed by systemd.
This example assumes an Ubuntu server already prepared and reachable by SSH, with PostgreSQL installed and compatible Elixir, Erlang, and Rust versions.
For the basic administration tools:
sudo apt update

sudo apt install -y \
  postgresql \
  postgresql-client \
  nginx \
  certbot \
  python3-certbot-nginx \
  ufw
First I create a PostgreSQL role and database dedicated to Supavisor's metadata:
sudo -u postgres createuser \
  --login \
  --pwprompt \
  supavisor

sudo -u postgres createdb \
  --owner=supavisor \
  supavisor
The role used for Supavisor's own metadata does not need to be a superuser.
An optional account that can create database roles from the dashboard is a different thing. Its privileges need to be separated and carefully protected.
Building the release
I've prepared a script in the repository:
./scripts/build-release.sh
It compiles the project, prepares the LiveView assets, and builds a production Elixir release.
The result is generated under:
_build/prod/rel/supavisor
The release must be built for an environment compatible with the destination server. I can't build on x86_64, copy it onto ARM64, and expect it to work.
Next I create a dedicated Linux user:
sudo adduser --system \
  --group \
  --home /var/lib/supavisor \
  supavisor
And install the release:
sudo mkdir -p /opt/supavisor

sudo cp -a \
  _build/prod/rel/supavisor \
  /opt/supavisor/current

sudo chown -R \
  supavisor:supavisor \
  /opt/supavisor/current
Configuring Supavisor
In production, the application reads its configuration from:
/etc/supavisor/supavisor.env
The repository already includes a template:
deploy/systemd/supavisor.env.example
Copy it:
sudo install -d -m 700 /etc/supavisor

sudo install -m 600 \
  deploy/systemd/supavisor.env.example \
  /etc/supavisor/supavisor.env

sudoedit /etc/supavisor/supavisor.env
Some important settings are:
PORT=4000

HTTP_BIND_ADDRESS=127.0.0.1
PROXY_BIND_ADDRESS=127.0.0.1

PROXY_PORT_TRANSACTION=6543
PROXY_PORT_SESSION=5452

ADMIN_BASE_URL=https://db.example.com
POOLER_HOST=db.example.com

ADMIN_EMAILS=admin@example.com

CLUSTER_POSTGRES=false
ADMIN_PROVISIONING_ENABLED=false
The real environment file also needs DATABASE_URL for the metadata database, SECRET_KEY_BASE, VAULT_ENC_KEY, JWT secrets, and the other parameters required by the template.
To generate some of them:
# Vault key: 32 hexadecimal characters
openssl rand -hex 16

# Phoenix secret
openssl rand -hex 64

# Other random secrets
openssl rand -hex 32
Don't copy the example development secrets.
In particular, keep a protected backup of VAULT_ENC_KEY. If you lose it, stored credentials encrypted by Supavisor may no longer be recoverable.
Starting it with systemd
There's already a systemd unit in the repository:
deploy/systemd/supavisor.service
Install it:
sudo cp \
  deploy/systemd/supavisor.service \
  /etc/systemd/system/

sudo systemctl daemon-reload

sudo systemctl enable --now supavisor
Check the service:
sudo systemctl status supavisor

sudo journalctl -u supavisor -f
The unit runs the metadata migrations before starting the application.
That means the supavisor metadata database must already exist and its configured credentials must work.
Firewall: a direct connection, not an open database
To use Supavisor from another server, I don't need to expose PostgreSQL to the whole Internet. I only need the pooler ports reachable from authorized application IPs. The Phoenix dashboard can continue listening on 127.0.0.1:4000 behind Nginx and HTTPS.
To avoid exposing the pooler before the network is secured, I initially leave PROXY_BIND_ADDRESS=127.0.0.1. Before changing it, I configure the firewall. The address 198.51.100.10 below is an example, not a real application IP; replace it with the application server's outgoing public IP.
sudo ufw allow OpenSSH
sudo ufw allow 80/tcp
sudo ufw allow 443/tcp

sudo ufw allow from 198.51.100.10 to any port 6543 proto tcp
sudo ufw allow from 198.51.100.10 to any port 5452 proto tcp

sudo ufw default deny incoming
sudo ufw default allow outgoing
sudo ufw enable
sudo ufw status verbose
PostgreSQL on 5432 stays private. Supavisor's internal ports, including 5412 and 12100 through 12107, must stay closed to the public as well. If a dedicated private-network interface is available, binding to it is preferable to listening on all interfaces.
I use Nginx for the web console. A minimal HTTP virtual host, before enabling a certificate, looks like this:
server {
    listen 80;
    server_name db.example.com;

    location / {
        proxy_pass http://127.0.0.1:4000;
        proxy_http_version 1.1;

        proxy_set_header Host $host;
        proxy_set_header X-Forwarded-Proto $scheme;
        proxy_set_header X-Forwarded-For $proxy_add_x_forwarded_for;

        proxy_set_header Upgrade $http_upgrade;
        proxy_set_header Connection "upgrade";

        proxy_read_timeout 3600;
    }
}
Once DNS and the virtual host are configured, I check Nginx and enable HTTPS:
sudo nginx -t
sudo systemctl reload nginx

sudo certbot --nginx -d db.example.com
I can then use the certificate for Supavisor's PostgreSQL listener as well. Supavisor runs under an unprivileged user, so I don't want to give it unrestricted access to Certbot's private directories. I copy the certificate and key to a dedicated directory with controlled permissions:
sudo install -d -m 750 -o root -g supavisor /etc/supavisor/tls

sudo install -m 644 -o root -g supavisor \
  /etc/letsencrypt/live/db.example.com/fullchain.pem \
  /etc/supavisor/tls/fullchain.pem

sudo install -m 640 -o root -g supavisor \
  /etc/letsencrypt/live/db.example.com/privkey.pem \
  /etc/supavisor/tls/privkey.pem
In Supavisor's environment file I enable the network listener and provide those certificates. I do this only after verifying the firewall rules:
PROXY_BIND_ADDRESS=0.0.0.0
PROXY_PORT_TRANSACTION=6543
PROXY_PORT_SESSION=5452

GLOBAL_DOWNSTREAM_CERT_PATH=/etc/supavisor/tls/fullchain.pem
GLOBAL_DOWNSTREAM_KEY_PATH=/etc/supavisor/tls/privkey.pem

TRUST_PROXY_HEADERS=true
The value 0.0.0.0 binds IPv4 listeners on all interfaces. That's why the firewall matters: only approved IPs should be allowed to reach 6543 and 5452. TRUST_PROXY_HEADERS=true is for the web console behind the local reverse proxy and should only be enabled when Nginx overwrites forwarded headers.
Restart Supavisor and verify the service:
sudo systemctl restart supavisor
sudo systemctl status supavisor
sudo ufw status verbose
The copied certificate must also be refreshed when Certbot renews it, for example with a deploy hook that copies the new files, verifies permissions, and restarts Supavisor. The browser reaches the dashboard over HTTPS through Nginx, while Ecto and other database clients use the encrypted PostgreSQL protocol directly on the pooler ports.
If the application runs on a platform with changing egress IPs, I'd consider a private network, VPN, or stable egress address before opening access to a broad IP range.
Signing in to the dashboard for the first time
The development login is convenient, but I obviously don't want anyone to open the dashboard in production.
My fork includes an administrative authorization system.
The console supports email and password and, optionally, GitHub OAuth sign-in.
There's no public administrator registration in production.
The initial allowlist of administrator email addresses comes from:
ADMIN_EMAILS=admin@example.com
After the first startup, a fresh installation can generate a one-time link on the server so an authorized administrator can set a password.
With the service running:
sudo systemd-run --wait --pipe --collect \
  -p User=supavisor \
  -p Group=supavisor \
  -p WorkingDirectory=/opt/supavisor/current \
  -p EnvironmentFile=/etc/supavisor/supavisor.env \
  /opt/supavisor/current/bin/supavisor rpc \
  '{:ok, url} = SupavisorWeb.AdminAuth.create_magic_link("admin@example.com"); IO.puts(url)'
That link must be kept private. It expires after 15 minutes and can only be used once.
I open it, set my password, and can then sign in normally. SMTP isn't required for password-based login.
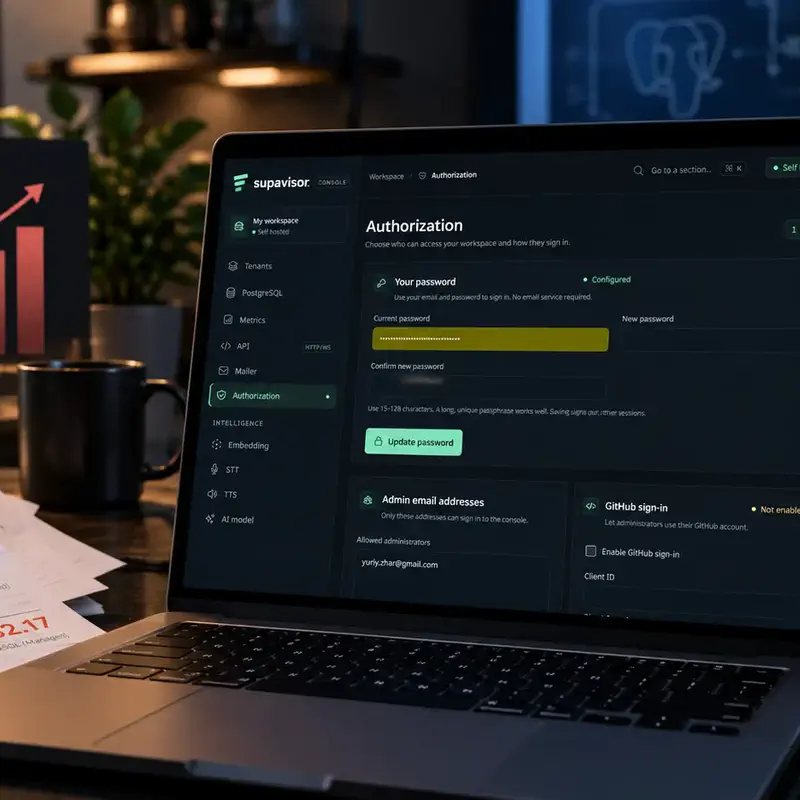
On the Authorization page, which I added with LiveView, I can change the password, review approved administrator addresses, and optionally configure GitHub as another sign-in method.
If I forget the password, the repository also contains an administrative password reset tool that runs on the server.
What matters to me is that I retain control of the setup without depending on an outside service to administer PostgreSQL.
Connecting to the server once everything is configured
At this point I have a server running PostgreSQL and Supavisor, a hostname such as db.example.com, a TLS certificate for that hostname, and a firewall allowing only the authorized application servers to reach the pooler.
To test the connection from the actual application machine, I don't need to SSH into the database server. I can connect directly using psql with certificate validation:
PGSSLMODE=verify-full \
PGSSLROOTCERT=/etc/my_app/tls/ca.crt \
psql \
  -h db.example.com \
  -p 6543 \
  -U demo_app.demo \
  -d demo_db \
  -W
I enter the tenant password and run:
SELECT current_database(), current_user;
If that query succeeds, the client can reach Supavisor directly over the network. Ecto uses the same connection parameters. Port 6543 is for transaction pooling; migrations can use 5452 with the same credentials and trusted certificate.
One distinction matters here. A direct PostgreSQL connection can also use client-certificate authentication, as I do in some of my applications. My current Supavisor fork, however, doesn't automatically require client certificates on its incoming TLS connections: the server handshake uses verify: :verify_none. That's why the tenant credentials and restrictive firewall rules are still essential. Simply copying client certificates from the old PostgreSQL connection doesn't reproduce its authentication policy.
An SSH tunnel remains an option, not a requirement. If I don't have a stable outgoing IP to allowlist, a private network or VPN may be more practical. But once TLS and the network are configured, the application connects directly to the server.
Running migrations
This is worth sorting out from the start.
Normal application queries can use transaction pooling as long as the application doesn't depend on session state surviving between transactions.
For migrations, I prefer session pooling or a direct PostgreSQL connection.
With the Ecto configuration above, I can change the mode:
DATABASE_POOL_MODE=session
In a Phoenix application with a regular release exposing Demo.Release.migrate/0, I can run:
DATABASE_POOL_MODE=session \
  bin/demo eval 'Demo.Release.migrate()'
The Demo.Release.migrate/0 function needs to exist in the release; Phoenix's release tooling can generate or help you adapt it.
For normal application traffic, I return to:
DATABASE_POOL_MODE=transaction \
  bin/demo start
I avoid transaction pooling for operations that need state to survive between transactions: certain temporary tables, LISTEN/NOTIFY, session-level settings, or session-scoped advisory locks.
That's a normal limitation of transaction pooling, not something unique to Elixir.
What if my database is already with another provider?
I don't have to start again from scratch.
For an existing PostgreSQL database, I can use pg_dump and pg_restore.
For example, after checking credentials and version compatibility:
pg_dump \
  "$OLD_DATABASE_URL" \
  --format=custom \
  --file=backup.dump
I create the destination database first, then restore through a direct connection to PostgreSQL:
pg_restore \
  --dbname="$NEW_DATABASE_URL_DIRECT" \
  --no-owner \
  --no-acl \
  --exit-on-error \
  backup.dump
Here NEW_DATABASE_URL_DIRECT must point to the new PostgreSQL server, not the transaction pool. Any required extensions and permissions need to be checked before the restore.
This is an example of a straightforward transfer, not a zero-downtime migration procedure.
If the old application continues writing during the dump, I need to plan the final cutover so changes made after the snapshot aren't lost.
I first test the restore into a separate database, check the schema and data, and only then arrange the application connection switch.
I don't delete the old service until I'm sure everything works.
Discovering that the backup was unusable is not a particularly fun way to end a migration.
So, is it worth it?
For me, yes.
I can now use PostgreSQL for multiple projects without automatically purchasing another managed database each time.
I can administer databases and tenants from the dashboard, monitor connections and metrics, make backups, and choose when the machine genuinely needs more resources.
And one of my favorite things about the whole setup is that Supavisor is written in Elixir.
I could take an existing open-source project, understand it, and add what I needed without writing a PostgreSQL connection pooler from scratch.
Of course, none of this is free.
I'm now responsible for updates, server availability, security, and especially backups. A backup on the same machine won't help if that machine disappears. I need off-server copies and actual restore tests.
And one server is still a single point of failure. Pooling improves connection management, but it doesn't magically distribute PostgreSQL or add CPU capacity.
For large or critical applications, managed infrastructure can absolutely be worth the price.
But for the way I work, with plenty of small projects and applications constantly changing, this approach makes a lot more sense.
And I have to say I'm quite happy with the dashboard, too.
It all started because I was tired of paying ridiculous amounts for PostgreSQL instances that often did little more than store a few bits of data.
Now I have my own server, my own connection pooler, and a LiveView console to manage it all.
Maybe one day one of my projects will grow enough to need a dedicated cluster and a more elaborate setup.
Great.
That would be pretty good news.
Until then, at least I can keep building without adding another subscription every time I have an idea.
And given how many ideas I have, it was about time.